The Handoff Checklist Engineering Uses to Launch Database Access for Ops and Marketing
Engineering creates the guardrails that let ops and marketing access data safely and independently.
For a small to midsize startup, a database interface for non-technical teams should provide governed access to readable reporting views. The engineering handoff makes that possible through an isolated read path, scoped permissions, clear metric definitions, onboarding, and ongoing guardrails. A no-SQL interface is the front door.
Why ops and marketing teams still can't get the data they need
Centralizing analytics makes sense when a team is small. But as requests accumulate, the data team becomes a ticket queue, and adding dashboards does not necessarily shorten it. Instead, the queue changes shape. A request to build a report becomes an interrupt-driven Slack message asking whether a number is safe to put in front of a customer.
Handing out database credentials looks like a shortcut. Yet non-technical users do not want a psql prompt, and broad production access opens the door to a DELETE without a WHERE clause or a support rep reading payment tokens. The tools failed, and the self-service model asked business users to understand too much and gave them too little context. Without a structured handoff, engineering must choose between remaining the gatekeeper and removing a gate that was doing useful work.
What engineering is actually signing up for when it runs this handoff
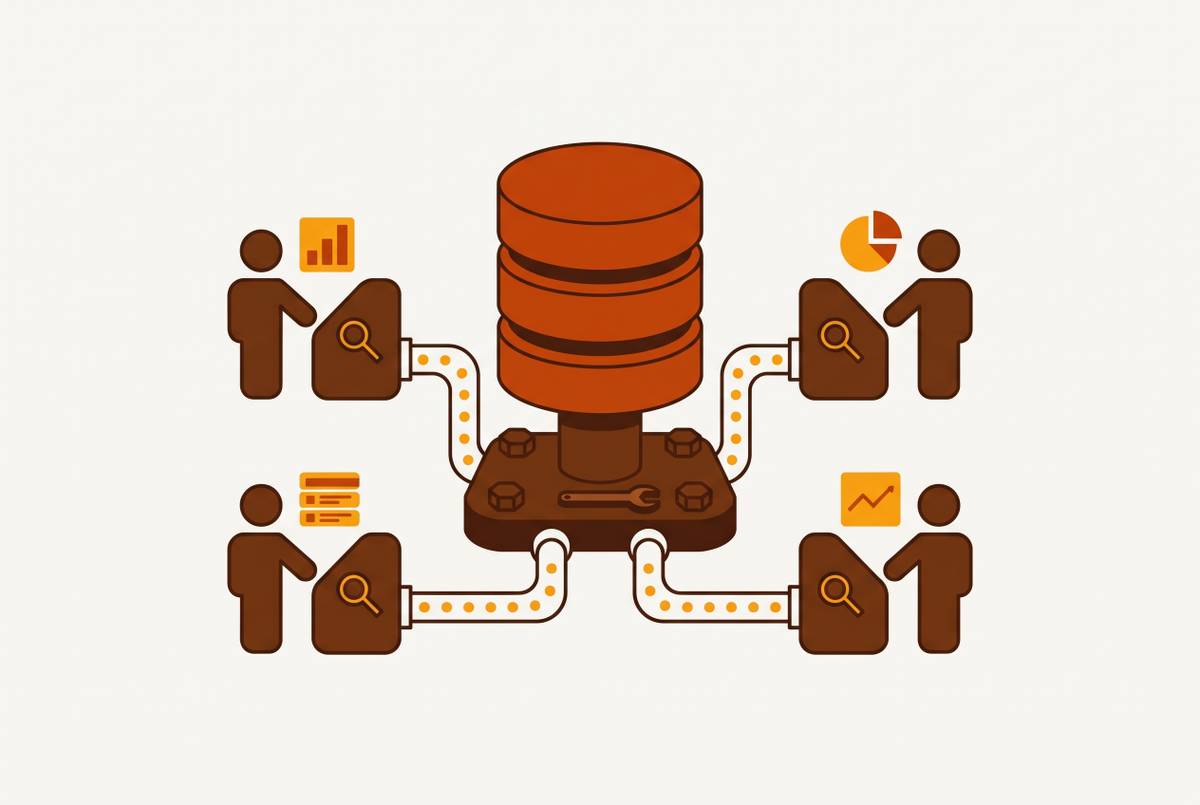
Engineering owns three layers of this handoff, namely the database layer, the permission layer, and the interface layer. Each addresses a different failure mode. The database layer separates analytical work from transactions so that an expensive report does not compete with the application. The permission layer controls what users can read as well as what they can change. The interface layer makes the exposed data understandable and its definitions consistent enough to trust.
These layers are related, but none substitutes for another. A view with a clear name can still show private customer data, while a connection with tight limits can still feed two dashboards whose numbers disagree. That is why all three must be ready for the access being launched before users receive it. Onboarding then explains the system, and recurring checks keep it intact. The engineering deliverable is a repeatable, auditable playbook.
Step 1 — Isolating the read path so analytics queries can't touch the production primary
To put the database layer in place, engineering should first create a dedicated read-only database role. Sharing one admin key across every chart and report lets reporting work do far more than it needs to. A read-only role stops writes while leaving read costs to be addressed separately. Point the analytics tool at a read replica rather than the production primary, so reporting queries run on a separate read workload.
Small internal dashboards with light query loads can connect directly to production without incident. The trouble arrives as dashboards scale and heavy analytical queries compete with transactional workloads during peak hours. A replica provides the clean separation point. Where one is unavailable, cache results or schedule refreshes during off-peak windows as interim mitigations. Those steps lower the risk, but the shared primary still handles both analytics and the application's work.
Next, set a query timeout on the analytics role, using statement_timeout in Postgres. A non-technical user cannot be expected to recognize that a cross-join over two large tables is expensive. A timeout cancels a bad query before it can pin CPU. Document replication lag in the handoff as well, since lag under a few seconds is standard for most managed setups, while anything over a minute risks stale numbers reaching a live report.
Step 2 — Building a permission layer where read-only actually means safe
A support rep can have read-only access and still run SELECT * FROM users, exposing password hashes, API keys, or PII. Nothing was changed, yet the boundary failed. To close that gap, engineering should scope readable data as deliberately as it scopes writes. Column grants are the starting point when the job is simply to hide a few columns.
For anything more complex, use views as the primary reporting surface. A view lets the user query the approved data without touching the underlying tables, joins, or sensitive columns. It also gives engineering a place to turn a messy schema into something legible. This is where safety and usability begin to reinforce each other. The same surface that excludes private fields can expose business-friendly names without changing the underlying tables.
Row-level security, or RLS, addresses a different boundary. In multi-tenant embedded analytics, where the non-technical users are customers, column grants cannot stop customer A from seeing customer B’s rows. Apply RLS so isolation lives in the database rather than in a WHERE clause that application code might forget. A missing filter should not hold the keys to an entire customer table.
Make ALTER DEFAULT PRIVILEGES a named checklist item. Without the default grants that give the read-only role access to new tables, those tables can stay hidden from it, so a missing permission can look like a broken report. Document how those defaults fit the intended reporting access rather than treating future tables as an afterthought. Plan for access reviews at regular intervals and for audit logging here too. They are the recurring upkeep of this boundary.
Step 3 — Defining metrics and naming conventions before anyone logs in
When two dashboards show numbers that disagree, users can suddenly lose trust in the whole data team. Which one is right, and why should either be trusted? Correct permissions cannot settle that dispute. Before opening access, engineering should establish one agreed meaning for each headline metric and make that meaning clear to users.
Start by checking whether someone outside engineering can make sense of the reporting surface. A table name that reads like an internal joke is not documentation, however good the joke. Business-friendly table and field names should tell users what they are looking at without requiring an analyst to translate warehouse shorthand. Use the views created in the permission step to rename columns and reshape the schema.
Skipping this work invites shadow analytics. Business teams build spreadsheets, copy data by hand, or paste results into external tools because they cannot make sense of the governed environment. Sensitive data can leave that environment in the process. Meanwhile, the data team receives more questions about whether numbers are right, undoing the relief that self-service was meant to provide. Practical definitions and readable views address this problem without waiting for a complete semantic layer.
As a 2026 addition to the checklist, text-to-SQL changes who writes the query while preserving the need for access controls. Point AI query tools at the restricted analytics role and curated reporting views, and keep them away from a superuser connection. A conversational interface is not a permission boundary.
The user onboarding sequence that turns access into actual self-service
With the three technical layers ready, the handoff turns to how people will use them. Access alone does not teach anyone what a view means or which question it can answer. Without structured onboarding, users go back to engineering as soon as they find a field they do not know. The bottleneck survives in a different costume. Engineering should therefore treat the walkthrough as part of completion before launch.
Begin with the available views and their business purpose. Explain which tables are exposed, what each field represents, and what questions each view is designed to answer. Then connect those examples to the naming conventions established before rollout, so users know what to look for elsewhere.
The walkthrough should also explain the guardrails in plain language. Users should know that they are connected through a read-only analytics role and why that prevents accidental deletes. Where database-level row permissions apply, explain that those permissions determine what each user sees in the interface, keeping the access model in one place. Finally, establish a single point of contact or documented channel for questions about definitions. It should help users understand definitions while keeping requests to run queries for them out of that queue.
Guardrails that prevent credential sprawl and accidental writes as the team grows
After onboarding, the remaining checklist items protect the setup from ordinary growth. Teams change roles, add reports, and create new tables. None of that requires a dramatic security incident to erode the original boundaries. Credential sprawl is the common long-term failure mode, beginning with one shared key and ending with nobody knowing who has access to what. Engineering should use one named analytics credential for each role and issue it through the tool, without creating or handing out credentials for each person.
Schema changes need the same routine attention. The default-privilege check from Step 2 belongs in this ongoing work because new tables need the intended grants. Otherwise, ops discovers the gap when a report breaks. Require change requests before teams change shared database tables or column names. Automated contract tests can check whether planned changes break downstream views, so engineering can catch problems before users see them.
Not every schema problem makes a report visibly fail. A renamed column or an undocumented new field can instead prompt the familiar question about why a number looks wrong. Treat schema drift as part of keeping the reporting contract in place. As the schema changes, the naming conventions and definitions set at launch must still help users understand the data, or the interface slowly becomes a puzzle that only the people who built it can solve.
Schedule access reviews. A support rep who moves into another role may retain access to a customer PII view that the new job does not require. Audit logging supplies evidence for those reviews, which otherwise become manual and incomplete. These checks are the tail of the handoff. Their purpose is to keep the launched access aligned with the people and data it now serves.
What the completed handoff actually changes for both teams
For a solo data engineer, query-writing speed is often not the constraint. Context-switching, repetitive requests, and being the only person with the necessary institutional knowledge consume the day. A completed handoff lets routine questions leave that queue while keeping the definitions and permissions that make their answers usable. Ops and marketing also have less need to move data by hand, so there are fewer chances for errors from uploads, incomplete downloads, and other processing steps. Independence becomes less about moving data around and more about asking questions where the governed data already lives.
Community Health Network illustrates the pattern at scale. Its governed self-serve rollout to a large group of clinical staff sharply reduced ad-hoc report requests, shifting work as the analytics team recovered most of its capacity for higher-order work. When users can answer routine questions themselves, analysts can move upstream into cohort behavior, margin structure, and questions nobody had thought to ask.
The strongest objection is that governance is itself an engineering project. Full semantic layers can take many months for enterprise teams, and a handoff that waits for perfection may never arrive on time. Starting with views and naming conventions delivers most of the benefit without requiring a finished semantic layer. Ship the checklist incrementally, completing the protections and definitions for each increment before opening it. That leaves analysts room to move upstream without asking ops and marketing to wait for the entire river to be mapped.